
Why AI Leaderboards Need Efficiency-Adjusted Rankings
Kimi K3's score per dollar shows a gap in how we rank AI models. Here is a finance-style, efficiency-adjusted way to rank them, and why it matters for careers.
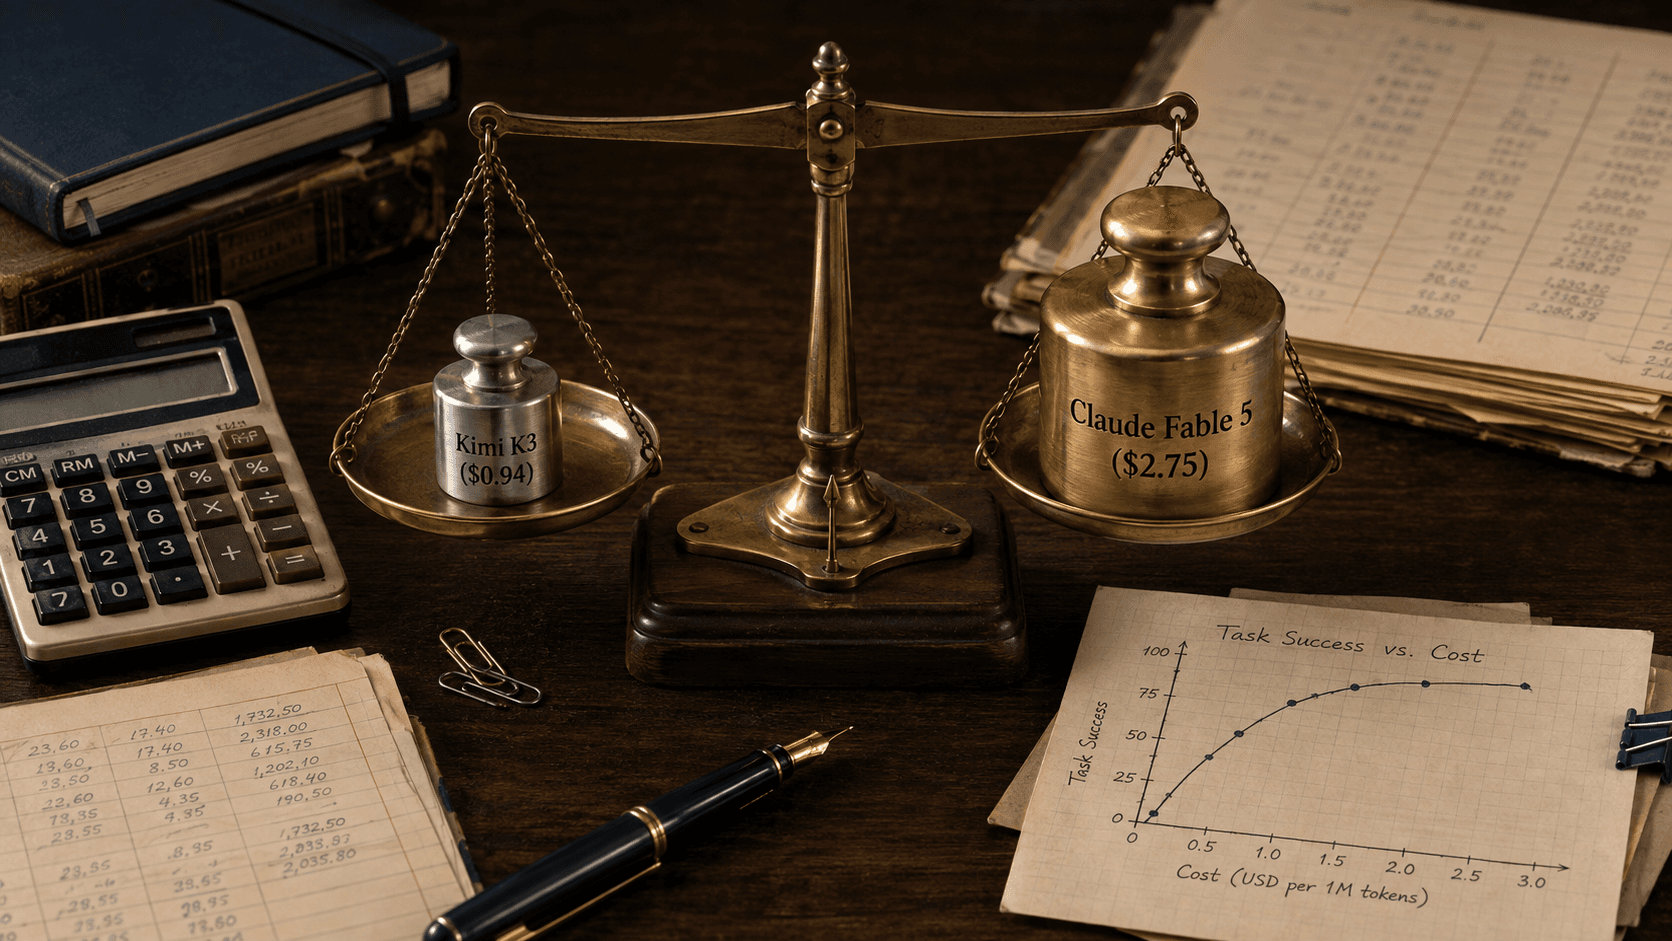
Last updated: August 2026.
Quick answer: Kimi K3 may be one of the strongest arguments yet for changing how we rank AI models. On the Artificial Analysis Intelligence Index it scored 57, only three points behind Claude Fable 5, yet its estimated cost per benchmark task was $0.94, against $2.75 for Fable 5. That gap exposes the limits of ranking models on answer quality alone. In production, cost, latency, reliability, and required human intervention matter too, so leaderboards may be ranking models by the wrong objective function. A finance-style, efficiency-adjusted ranking (reliable task success per dollar and per second) would capture what they currently miss.
The instinctive reading of a result like this is geopolitical: another sign of intensifying global AI competition, another challenger closing the gap with the frontier. That reading is partly right, but it misses what the numbers say about how we rank models.
What Did Kimi K3 Show?
Two numbers matter here. On the Artificial Analysis Intelligence Index, Kimi K3 scored 57, only three points behind Claude Fable 5, the public configuration built on the same underlying model as Mythos 5. And Artificial Analysis's estimated cost per benchmark task came in at $0.94 for Kimi K3, compared with $2.75 for Fable 5.
So Kimi K3 gives up three points of measured intelligence and costs roughly a third as much per task. For a single benchmark query, the difference hardly matters. A production system running thousands of tasks a day pays the cost gap on every task, so it adds up fast and can decide which model you choose. Yet the leaderboard headline (the number that shapes procurement decisions, press coverage, and engineering defaults) reflects only one axis of that trade.
Are We Ranking AI Models With the Right Objective Function?
Answer quality and task completion are only part of the equation. They are the part that is easiest to measure in a lab, which is largely why leaderboards are built around them. But if you have shipped an AI feature, you know the production equation has more terms:
- Cost. What does each completed task cost at your volume?
- Latency. Does the answer arrive while it still matters?
- Reliability. How often does the system succeed without a human stepping in?
- Intervention. When it fails, how expensive is the failure to catch and fix?
A model can lead on measured intelligence and still lose on every one of these axes for a given workload. Ranking on quality alone is like ranking cars purely on top speed. Top speed is useful information, but it is the wrong objective function when you are choosing a car to drive every day.
What Can Finance Teach AI Evaluation?
Finance solved a version of this problem decades ago. We rarely judge a strategy by its gross return alone. We look at the Sharpe ratio (return per unit of risk) and at returns after transaction costs. Practitioners also know that a highly accurate prediction may still have little trading value if it arrives after the market has moved.
AI evaluation needs the same discipline: efficiency-adjusted metrics such as reliable task success per dollar and per second. Each finance concept has a direct counterpart:
| Finance concept | AI evaluation equivalent |
|---|---|
| Gross return | Raw benchmark score |
| Sharpe ratio (risk-adjusted return) | Reliable task success rate, not best-case quality |
| Returns after transaction costs | Task value after compute cost |
| A correct prediction that arrives too late | An accurate answer delivered past its latency budget |
| Portfolio construction | Workflow design: routing, verification, guardrails |
A leaderboard gives you a single ranked list. Under this framework, model choice becomes a portfolio question: what combination of components delivers the most dependable value for the resources spent?
Can a Workflow Beat a Frontier Model?
Under efficiency-adjusted thinking, a cheaper and faster model inside a carefully designed agentic workflow can deliver more real-world value than Mythos 5 behind one expensive, inefficient prompt. Decomposition, model routing, retrieval, tool use, verification, retries, and guardrails can matter as much as raw model intelligence.
If workflow design can move outcomes as much as model choice, teams should put more of their effort into it. Access to the best models is becoming common, so the scarce skill is the engineering judgment to build reliable systems out of imperfect parts. We made a version of this argument from the product side in why a career tool beats a general chatbot: a focused system around the model can outperform a stronger model used naively.
This is also how we think about model selection at PokeBot: run text features on a fast, efficient model at a low reasoning setting instead of the largest one available, give speech its own dedicated models, then optimize the entire workflow around reliable user outcomes. Treating every step as if it needs frontier reasoning just spends the user's patience and the company's compute on the wrong objective.
Why Should Job Seekers Care About Any of This?
Because efficiency-adjusted thinking is starting to set some candidates apart, and many job seekers have not noticed yet.
At many companies, system design interviews now include AI components, and AI product roles revolve around these same trade-offs: cost budgets, latency budgets, reliability targets, escalation paths. Knowing which model tops a leaderboard no longer impresses many of those interviewers. They want to hear the reasoning behind your choice. Compare these two answers:
Weak answer:
"I'd use the most capable frontier model for this feature. It has the highest benchmark scores, so it will give users the best results."
Strong answer:
"I'd start from the task budget: what does a completed task need to cost, and how fast must it feel? Then I'd decompose the feature: route classification and extraction to a cheap fast model, reserve the expensive model for the one step that needs deep reasoning, add a verification pass and a retry policy, and define when a human gets pulled in. I'd measure reliable task success per dollar, not raw answer quality."
In finance terms, the weak answer optimizes gross return and the strong answer optimizes the Sharpe ratio. The strong answer also shows that you think in systems and constraints, which is what many interviewers for these roles are listening for. The same reasoning applies outside engineering: product managers defending a build decision, analysts choosing tooling, operators justifying spend. If AI is redefining what high performers look like, as we argued in AI won't replace you, it raises the bar, efficiency-adjusted judgment is one of the clearest examples of that higher bar.
The next AI leaderboard worth building would rank whole systems as well as models, by reliable task value after cost, latency, and operational friction. Until someone builds it, people who can do that ranking in their heads have an edge in architecture reviews and in interviews.
If you want to practice making that argument under pressure, PokeBot's Interview Practice lets you rehearse Technical questions (including system design) and Product Sense questions out loud with scored feedback, before a real interviewer asks.
Frequently Asked Questions
What is an efficiency-adjusted AI ranking?
A way of ranking AI models or systems that accounts for more than answer quality. Instead of asking only 'how smart is the model?', it asks 'how much reliable task value does this system deliver per dollar and per second, after accounting for reliability and the human intervention it still requires?' It is like judging an investment strategy by its Sharpe ratio and its returns after costs, rather than by gross return alone.
Why did Kimi K3 spark this debate?
Kimi K3 scored 57 on the Artificial Analysis Intelligence Index, only three points behind Claude Fable 5, while its estimated cost per benchmark task was $0.94 compared with $2.75 for Fable 5. A model that close on measured intelligence, at a fraction of the cost per task, makes rankings that ignore cost look incomplete.
Don't benchmark scores already tell us which model is best?
They tell us part of the story: answer quality and task completion under benchmark conditions. In production, cost, latency, reliability, and how much human intervention a system needs also determine value. Two models with similar scores can deliver very different real-world results once those factors are counted.
What is the finance analogy for ranking AI models?
Finance rarely judges a strategy by gross return alone. Practitioners look at risk-adjusted measures like the Sharpe ratio and at returns after transaction costs, and they know a highly accurate prediction can have little trading value if it arrives after the market has moved. AI evaluation needs the same discipline: adjust quality for cost, speed, and reliability before comparing models.
Can a cheaper model really beat a frontier model in practice?
Inside a carefully designed agentic workflow, yes. Decomposition, model routing, retrieval, tool use, verification, retries, and guardrails can matter as much as raw model intelligence. A cheaper, faster model orchestrated well can deliver more real-world value than a frontier model behind one expensive, inefficient prompt.
How does PokeBot apply efficiency-adjusted thinking?
PokeBot runs its text features on a fast, efficient model at a low reasoning setting instead of the largest model available, and gives speech its own dedicated models. The design goal is dependable results per unit of cost and time.
Why does efficiency-adjusted thinking matter for my career?
Because many employers, especially for AI-related roles, are starting to test for this kind of reasoning. At many companies, system design interviews now include AI components, and AI product roles revolve around cost, latency, and reliability trade-offs. A candidate who can argue 'which system delivers reliable value per dollar' stands out from candidates who only know which model tops the leaderboard.
How can I practice efficiency-adjusted reasoning for interviews?
Take a real task and design two versions: one built on a single call to the strongest model, one decomposed across cheaper models with routing, verification, and retries. Practice defending the trade-offs out loud: cost, speed, failure modes, and where a human checks the output. Mock interviews with feedback are a fast way to sharpen that argument.